Rollup Tables for Aggregation
Overview
Rollup tables provide automatic time-based aggregation of tag data, dramatically improving query performance for analytics and reporting. Instead of scanning millions of raw records, rollup tables pre-calculate statistics at different time intervals.
Time-Axis Feature Only
ROLLUP is available only for time-axis (BASETIME, BASE TIME) tag tables. The following features are not supported on distance-axis (BASE DISTANCE, BASEDISTANCE) tag tables.
WITH ROLLUP(...)CREATE ROLLUP ... ON <distance_tag> ...CREATE ROLLUP ... INTO (...) AS (...)
For example, the following statement fails.
CREATE TAG TABLE trip_rollup_test (
    name        VARCHAR(20) PRIMARY KEY,
    distance_m  DOUBLE BASE DISTANCE,
    value       DOUBLE SUMMARIZED
) WITH ROLLUP(SEC);

[ERR-04999: ROLLUP is not supported on DISTANCE axis TAG table.]
For distance-axis tables, use these patterns instead.
- Direct range queries with
BETWEEN a AND b - Bucket aggregation with
TRUNC(distance / bucket, 0) * bucket EXPLAINto verify that the distance predicate is used as a key range
Creating Rollup Tables
Creating a tag table does not create rollups by default. Create them yourself with the following syntax.
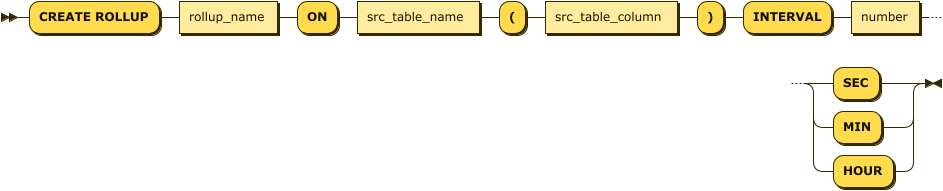
Public syntax:
CREATE ROLLUP [IF NOT EXISTS] rollup_name
  ON source_table(column_name)
  INTERVAL n (SEC|MIN|HOUR)
  [WAKEUP INTERVAL m (SEC|MIN|HOUR)]
  [EXTENSION]
  [WHERE predicate];

CREATE ROLLUP [IF NOT EXISTS] rollup_name
  ON source_table(json_column->'$.path')
  INTERVAL n (SEC|MIN|HOUR)
  [WAKEUP INTERVAL m (SEC|MIN|HOUR)]
  [WHERE predicate];

CREATE ROLLUP [IF NOT EXISTS] rollup_name
  FROM source_rollup_table
  INTERVAL n (SEC|MIN|HOUR)
  [WAKEUP INTERVAL m (SEC|MIN|HOUR)]
  [EXTENSION]
[WHERE predicate];- rollup name : name of the rollup table (any string of up to 40 characters)
- source table name : name of the source table whose data the rollup aggregates
- src_table_column : name of the column to aggregate
- By default, only numeric columns are supported.
JSON SUMMARIZEDis supported as a special mode that aggregates the whole JSON document invalue.- If the source table is a rollup table, omit it; the rollup target column of the source table is used automatically.
- number sec/min/hour : aggregation interval and its time unit
ex) 1 sec aggregate : 1 sec
ex) 30 seconds aggregate : 30 sec
ex) 1 minute aggregate : 1 min
ex) 1 hour aggregate : 1 hour - constraint
- The source table can only be a tag table or a rollup table.
- If the source table is a rollup table, the interval of the new rollup must be larger than the interval of the source table and must be a multiple of it.
Example of creating rollup tables
Mach> CREATE TAG TABLE tag (name VARCHAR(20) PRIMARY KEY, time DATETIME BASETIME, value DOUBLE, strvalue VARCHAR(20));
Executed successfully.

-- creating 1 second rollup for tag table
Mach> CREATE ROLLUP _tag_rollup_sec ON tag(value) INTERVAL 1 SEC;

-- creating 1 minute rollup for tag table
Mach> CREATE ROLLUP _tag_rollup_min ON tag(value) INTERVAL 1 MIN;

-- creating 1 hour rollup for tag table
Mach> CREATE ROLLUP _tag_rollup_hour ON tag(value) INTERVAL 1 HOUR;

-- creating 30 seconds rollup for tag table
Mach> CREATE ROLLUP _tag_rollup_30sec ON tag(value) INTERVAL 30 SEC;

-- creating 10 minutes rollup for roll up table above
Mach> CREATE ROLLUP _tag_rollup_10min ON _tag_rollup_30sec INTERVAL 10 MIN;

-- Error when creating rollup for non-numeric type columns
Mach> CREATE ROLLUP _tag_rollup_sec ON tag(strvalue) INTERVAL 1 SEC;
[ERR-02671: Invalid type for ROLLUP column (STRVALUE).]
Automatically create a ROLLUP table
You can create rollup tables automatically with the WITH ROLLUP (time_unit) keyword.
CREATE TAG TABLE tagtbl (name VARCHAR(20) PRIMARY KEY, time DATETIME BASETIME, value DOUBLE SUMMARIZED) WITH ROLLUP (time_unit)

time_unit := {SEC|MIN|HOUR}
If time_unit is omitted as below, SEC is used.
CREATE TAG TABLE tagtbl (name VARCHAR(20) PRIMARY KEY, time DATETIME BASETIME, value DOUBLE SUMMARIZED) WITH ROLLUPAutomatically created rollups are named in the following format. (tagtbl is the tag table name.)
- _
tagtbl_ROLLUP_SEC - _
tagtbl_ROLLUP_MIN - _
tagtbl_ROLLUP_HOUR
Mach> CREATE TAG TABLE tagtbl (name VARCHAR(20) PRIMARY KEY, time DATETIME BASETIME, value DOUBLE SUMMARIZED) WITH ROLLUP (SEC)

Mach> SHOW TABLES;
USER_NAME             DB_NAME                                             TABLE_NAME                                          TABLE_TYPE
-----------------------------------------------------------------------------------------------------------------------------------------------
SYS                   MACHBASEDB                                          TAGTBL                                              TAGDATA
SYS                   MACHBASEDB                                          _TAGTBL_DATA_0                                      KEYVALUE
SYS                   MACHBASEDB                                          _TAGTBL_DATA_1                                      KEYVALUE
SYS                   MACHBASEDB                                          _TAGTBL_DATA_2                                      KEYVALUE
SYS                   MACHBASEDB                                          _TAGTBL_DATA_3                                      KEYVALUE
SYS                   MACHBASEDB                                          _TAGTBL_META                                        LOOKUP
SYS                   MACHBASEDB                                          _TAGTBL_ROLLUP_HOUR                                 KEYVALUE
SYS                   MACHBASEDB                                          _TAGTBL_ROLLUP_MIN                                  KEYVALUE
SYS                   MACHBASEDB                                          _TAGTBL_ROLLUP_SEC                                  KEYVALUE
[9] row(s) selected.
Elapsed time: 0.001
Mach>
The unit given in time_unit is treated as the smallest unit, and rollups for the larger time units are created automatically as well.
When a rollup table name conflict occurs, all rollup table creation fails and only tag tables are generated.
When rollups are created automatically, you can set their DATA_PART_SIZE in bytes.
CREATE TAG TABLE tagtbl (name VARCHAR(20) PRIMARY KEY, time DATETIME BASETIME, value DOUBLE SUMMARIZED) WITH ROLLUP ROLLUP_DATA_PART_SIZE=(data_part_size)Extended ROLLUP
Add the EXTENSION keyword at the end of the rollup creation syntax to create an extended rollup.
An extended rollup also stores the first and last values of each interval.
-- Manually create an Extended Rollup table
CREATE ROLLUP _tag_rollup_sec ON tag(value) INTERVAL 1 SEC EXTENSION;

-- Automatically generate Extended Rollup tables
CREATE TAG TABLE tagtbl (name VARCHAR(20) PRIMARY KEY, time DATETIME BASETIME, value DOUBLE SUMMARIZED) WITH ROLLUP EXTENSION;
Conditional Rollups, Filters, and Hints
What this feature solves
When multiple rollups share the same interval, value column, and JSON path, the engine distinguishes between “plain” rollups and “filtered” rollups. It automatically prefers the unfiltered one, and you can force a specific rollup with a hint. Filters are validated at creation time, so confusing or unsafe definitions are rejected immediately.
How to create a filtered rollup
CREATE ROLLUP <rollup_name>
  ( ON <table_name>(<value_col>)
  | FROM <src_rollup_table_name> )
  INTERVAL <n> <SEC|MIN|HOUR>
WHERE <predicate>;- The predicate is applied to source rows before aggregation; predicate columns are not stored in the rollup table.
- Allowed: regular scalar expressions (AND/OR/NOT, comparison, BETWEEN, IN, LIKE, CASE, non-aggregate functions) that reference existing columns, including non‑summarized columns such as
value2orstatus. - Not allowed: subqueries, aggregate functions, unknown columns, or the tag-name (PK) column of a tag table (it is internally numeric, so string comparison is meaningless).
- Validation happens during
CREATE ROLLUP; invalid predicates fail fast with an error.
WHERE in conditional rollup vs custom rollup
- Conditional rollup uses an external
WHEREwith theON/FROMsyntax. - Custom Rollup (
INTO ... AS (SELECT ...)) supportsWHEREonly inside theSELECT. - Therefore,
CREATE ROLLUP ... INTO (...) AS (...) INTERVAL ... WHERE ...is not valid. - See Custom Rollup: User-Defined Aggregation and DDL: CREATE ROLLUP for the full syntax.
Automatic selection order (no hint)
- If a
ROLLUP_TABLE(<rollup_table_name>)hint exists, it always wins. - Otherwise, among rollups that match interval/value/JSON path, one without a predicate is chosen first.
- If no plain rollup exists, a predicate rollup is used.
- If multiple candidates remain, the existing rule is kept: pick the largest frequency that divides the requested interval; for equal frequencies, the first registered rollup stays selected.
Quick recipe (mirrors the regression scenario)
- Create a tag table with extra columns you want to filter on, for example
value2 DOUBLE,status INTEGERin addition to the summarizedvalue. - Create both plain and filtered rollups:
CREATE ROLLUP _tag_rollup_plain_1s      ON tag_bulk(value) INTERVAL 1 SEC;
CREATE ROLLUP _tag_rollup_plain_1m      FROM _tag_rollup_plain_1s INTERVAL 1 MIN;
CREATE ROLLUP _tag_rollup_cond_1s       ON tag_bulk(value) INTERVAL 1 SEC
  WHERE value2 >= 50 AND status >= 2;
CREATE ROLLUP _tag_rollup_cond_1m       FROM _tag_rollup_cond_1s INTERVAL 1 MIN;

-- Extended rollups for FIRST()/LAST()
CREATE ROLLUP _tag_rollup_plain_1s_ext  ON tag_bulk(value) INTERVAL 1 SEC EXTENSION;
CREATE ROLLUP _tag_rollup_cond_1s_ext   ON tag_bulk(value) INTERVAL 1 SEC EXTENSION
WHERE value2 >= 50 AND status >= 2;- Load data (bulk loader or INSERT), then flush to make aggregates available. Run
ROLLUP_FORCEon_TAG_BULK_ROLLUP_SEConly if the source table was created withWITH ROLLUP.
EXEC ROLLUP_FORCE(_TAG_BULK_ROLLUP_SEC);   -- auto rollup from WITH ROLLUP
EXEC ROLLUP_FORCE(_tag_rollup_plain_1s);
EXEC ROLLUP_FORCE(_tag_rollup_cond_1s);- Query without a hint (uses the plain rollup automatically):
SELECT rollup('sec', 30, time) AS rt, AVG(value), COUNT(value)
FROM   tag_bulk
WHERE  name = 'dev9' AND time BETWEEN '2020-01-02 00:00:00' AND '2020-01-02 00:10:00'
GROUP BY rt
ORDER BY rt;- Force a filtered rollup when you must honor the predicate:
SELECT /*+ ROLLUP_TABLE(_tag_rollup_cond_1s) */
       rollup('sec', 30, time) AS rt, AVG(value), COUNT(value)
FROM   tag_bulk
WHERE  name = 'dev9' AND time BETWEEN '2020-01-02 00:00:00' AND '2020-01-02 00:10:00'
GROUP BY rt
ORDER BY rt;- Using FIRST()/LAST()? Point the hint to an
EXTENSIONrollup; the functions are not available on non-extension rollups.
Metadata and upgrade notes
V$ROLLUPnow shows aPREDICATEcolumn so you can confirm which filter a rollup was created with.- The meta version is bumped to 10.0 to add this column. On the first server start after the upgrade, the catalog is altered automatically. If the upgrade fails (for example, because the meta is very old or corrupted), stop the server, keep the original database intact, restore or migrate the data into a new database, and recreate the rollups.
- Rollup creation still enforces the existing rules on intervals (multiples) and value types (numeric); filters do not change those constraints.
Start/Stop Rollup Table
When a rollup is created its worker thread starts automatically. You can toggle it later with either the stored procedures or the SQL syntax.
-- Start/stop a rollup
ALTER ROLLUP <rollup_name> START;
ALTER ROLLUP <rollup_name> STOP;

-- Equivalent procedures
EXEC ROLLUP_START(<rollup_name>);
EXEC ROLLUP_STOP(<rollup_name>);
Wakeup interval and scheduling
- Each rollup wakes up on its own schedule. By default, the wakeup interval equals the rollup interval, but you can shorten it (to a divisor of the rollup interval, so it stays aligned to the rollup boundary) to run more often.
- Syntax to change the wakeup interval:
ALTER ROLLUP <rollup_name> SET WAKEUP INTERVAL <N> (SEC|MIN|HOUR);Nmust be > 0.Nconverted to seconds must be no larger than the rollup interval.- The rollup interval must be an exact multiple of the wakeup interval; otherwise an error is raised.
- When changed, the thread wakes immediately and reschedules the next wakeup.
- Observability:
V$ROLLUPexposesWAKEUP_INTERVAL,LAST_WAKEUP_TIME,NEXT_WAKEUP_TIME, andRUN_STATE(INIT/SLEEPING/RUNNING).show rollupgapalso shows the last/next wakeup and run state.
Collect Rollup Instantly
By default, a rollup aggregates data at its configured time interval.
- ex) A 1-hour rollup aggregates data once an hour and waits for the rest of the time.
You can skip the wait and force aggregation manually.
-- Non-blocking: just wake the thread now, then return
ALTER ROLLUP <rollup_name> WAKEUP;

-- Blocking: run rollup immediately and wait for completion
ALTER ROLLUP <rollup_name> FORCE;
-- Equivalent procedure
EXEC ROLLUP_FORCE(<rollup_name>);
Rollup Rebuild Reference
Deleting raw TAG data or reloading corrected rows does not automatically rewind existing rollup results.
For built-in time-range recovery, EXEC ROLLUP_REBUILD(...), and manual custom rollup recovery steps, see Rollup Rebuild Guide.
Drop Rollup
Drops a rollup.
DROP ROLLUP rollup_name- rollup_name : name of the rollup to drop
- constraint: if another rollup uses the rollup to be dropped as its source, the drop fails with an error. When rollups depend on each other, drop them in the reverse order of creation.
mach> create tag table tag (name varchar(20) primary key, time datetime basetime, value double summarized);
mach> create rollup _tag_rollup_1 on tag(value) interval 1 sec;
mach> create rollup _tag_rollup_2 on _tag_rollup_1 interval 1 min;
mach> create rollup _tag_rollup_3 on _tag_rollup_2 interval 1 hour;

When created as above, the reference order is as follows.

tag -> _tag_rollup_1 -> _tag_rollup_2 -> _tag_rollup_3

At this time, if you try to delete the tag table or rollup in the middle, an error occurs.

mach> drop table tag
> [ERR-02651: Dependent ROLLUP table exists.]
mach> drop rollup _tag_rollup_1
> [ERR-02651: Dependent ROLLUP table exists.]

User must delete them in the following order to delete them normally.

mach> drop rollup _tag_rollup_3;
mach> drop rollup _tag_rollup_2;
mach> drop rollup _tag_rollup_1;
mach> drop table tag;
When deleting the TAG table, delete the ROLLUP table together
If you drop a tag table with the CASCADE keyword, the rollup tables that depend on it are dropped as well.
DROP TABLE TAG CASCADE;Mach> SHOW TABLES;
USER_NAME DB_NAME TABLE_NAME TABLE_TYPE
-----------------------------------------------------------------------------------------------------------------------------------------------
SYS MACHBASEDB TAGTBL TAGDATA
SYS MACHBASEDB _TAGTBL_DATA_0 KEYVALUE
SYS MACHBASEDB _TAGTBL_DATA_1 KEYVALUE
SYS MACHBASEDB _TAGTBL_DATA_2 KEYVALUE
SYS MACHBASEDB _TAGTBL_DATA_3 KEYVALUE
SYS MACHBASEDB _TAGTBL_META LOOKUP
SYS MACHBASEDB _TAGTBL_ROLLUP_HOUR KEYVALUE
SYS MACHBASEDB _TAGTBL_ROLLUP_MIN KEYVALUE
SYS MACHBASEDB _TAGTBL_ROLLUP_SEC KEYVALUE
[9] row(s) selected.
Elapsed time: 0.001
Mach>
Mach> DROP TABLE tagtbl CASCADE;
Dropped successfully.
Mach> show tables;
USER_NAME DB_NAME TABLE_NAME TABLE_TYPE
-----------------------------------------------------------------------------------------------------------------------------------------------
[0] row(s) selected.Syntax
rollup_expr := ROLLUP(time_unit, period, basetime_column [, origin])

--ex)
SELECT ROLLUP('MIN', 30, time, '1970-01-01'), MIN(value), MAX(value), AVG(value) FROM tag ..
When you use the ROLLUP keyword as above, the data is read from the matching rollup table.
- time_unit: any time unit available in the DATE_BIN() function
- period: the length of each interval in
time_unit, within the range that DATE_BIN() allows for that unit - basetime_column: DATETIME column of the TAG table specified with the
BASETIMEattribute - origin: the base time used to divide the ROLLUP time intervals. If omitted, it defaults to
1970-01-01 00:00:00.
Deprecated (version <= 8.0.19)
In version 8.0.19 and earlier, use the following ROLLUP expression.rollup_expr := basetime_column ROLLUP n time_unit -- ex) SELECT time ROLLUP 30 MIN, MIN(value), MAX(value), AVG(value) FROM tag ..
As above, appending the ROLLUP clause after the DATETIME column specified with the BASETIME attribute makes the query read from a rollup table.
The rollup table that is queried depends on TIME_UNIT.
| unit of time(Abbreviation) | rollup table |
|---|---|
| nanosecond (nsec) | SECOND |
| microsecond (usec) | SECOND |
| millisecond (msec) | SECOND |
| second (sec) | SECOND |
| minute (min) | MINUTE |
| hour | HOUR |
| day | HOUR |
| week | HOUR |
| month | HOUR |
| year | HOUR |
Because the ROLLUP clause reads the rollup table directly, aggregate functions have the following characteristics.
- Aggregate functions must be called on a numeric column. Only the six aggregate functions supported by rollup tables (SUM, COUNT, MIN, MAX, AVG, SUMSQ) are available.
- Extended rollups additionally support FIRST and LAST.
- GROUP BY must be applied directly to the BASETIME column used in ROLLUP.
- You can repeat the same ROLLUP clause in GROUP BY.
- Alternatively, give the ROLLUP clause an alias and use the alias in GROUP BY.
SELECT   rollup('sec', 3, time) mtime, avg(value)
FROM     TAG
GROUP BY mtime;

-- deprecated
SELECT   time rollup 3 sec mtime, avg(value)
FROM     TAG
GROUP BY time rollup 3 sec mtime;

-- or
SELECT   time rollup 3 sec mtime, avg(value)
FROM     TAG
GROUP BY mtime;
Data Sample
Below is the sample data for the rollup examples.
create tag table TAG (name varchar(20) primary key, time datetime basetime, value double summarized) with rollup extension;

insert into tag metadata values ('TAG_0001');

insert into tag values('TAG_0001', '2018-01-01 01:00:01 000:000:000', 1);
insert into tag values('TAG_0001', '2018-01-01 01:00:02 000:000:000', 2);
insert into tag values('TAG_0001', '2018-01-01 01:01:01 000:000:000', 3);
insert into tag values('TAG_0001', '2018-01-01 01:01:02 000:000:000', 4);
insert into tag values('TAG_0001', '2018-01-01 01:02:01 000:000:000', 5);
insert into tag values('TAG_0001', '2018-01-01 01:02:02 000:000:000', 6);

insert into tag values('TAG_0001', '2018-01-01 02:00:01 000:000:000', 1);
insert into tag values('TAG_0001', '2018-01-01 02:00:02 000:000:000', 2);
insert into tag values('TAG_0001', '2018-01-01 02:01:01 000:000:000', 3);
insert into tag values('TAG_0001', '2018-01-01 02:01:02 000:000:000', 4);
insert into tag values('TAG_0001', '2018-01-01 02:02:01 000:000:000', 5);
insert into tag values('TAG_0001', '2018-01-01 02:02:02 000:000:000', 6);

insert into tag values('TAG_0001', '2018-01-01 03:00:01 000:000:000', 1);
insert into tag values('TAG_0001', '2018-01-01 03:00:02 000:000:000', 2);
insert into tag values('TAG_0001', '2018-01-01 03:01:01 000:000:000', 3);
insert into tag values('TAG_0001', '2018-01-01 03:01:02 000:000:000', 4);
insert into tag values('TAG_0001', '2018-01-01 03:02:01 000:000:000', 5);
insert into tag values('TAG_0001', '2018-01-01 03:02:02 000:000:000', 6);
For one tag, 18 rows with different values were entered at one-second resolution, spread across three hourly buckets. To check the results right after inserting, run EXEC ROLLUP_FORCE(_TAG_ROLLUP_SEC), EXEC ROLLUP_FORCE(_TAG_ROLLUP_MIN), and EXEC ROLLUP_FORCE(_TAG_ROLLUP_HOUR) in that order.
Get ROLLUP AVG
The following example gets the per-second, per-minute, and per-hour averages for the tag.
Mach> SELECT rollup('sec', 1, time) as mtime, avg(value) FROM TAG WHERE name = 'TAG_0001' group by mtime order by mtime;
mtime                           avg(value)
---------------------------------------------------------------
2018-01-01 01:00:01 000:000:000 1
2018-01-01 01:00:02 000:000:000 2
2018-01-01 01:01:01 000:000:000 3
2018-01-01 01:01:02 000:000:000 4
2018-01-01 01:02:01 000:000:000 5
2018-01-01 01:02:02 000:000:000 6
2018-01-01 02:00:01 000:000:000 1
2018-01-01 02:00:02 000:000:000 2
2018-01-01 02:01:01 000:000:000 3
2018-01-01 02:01:02 000:000:000 4
2018-01-01 02:02:01 000:000:000 5
2018-01-01 02:02:02 000:000:000 6
2018-01-01 03:00:01 000:000:000 1
2018-01-01 03:00:02 000:000:000 2
2018-01-01 03:01:01 000:000:000 3
2018-01-01 03:01:02 000:000:000 4
2018-01-01 03:02:01 000:000:000 5
2018-01-01 03:02:02 000:000:000 6
[18] row(s) selected.

Mach> SELECT rollup('min', 1, time) as mtime, avg(value) FROM TAG WHERE name = 'TAG_0001' group by mtime order by mtime;
mtime                           avg(value)
---------------------------------------------------------------
2018-01-01 01:00:00 000:000:000 1.5
2018-01-01 01:01:00 000:000:000 3.5
2018-01-01 01:02:00 000:000:000 5.5
2018-01-01 02:00:00 000:000:000 1.5
2018-01-01 02:01:00 000:000:000 3.5
2018-01-01 02:02:00 000:000:000 5.5
2018-01-01 03:00:00 000:000:000 1.5
2018-01-01 03:01:00 000:000:000 3.5
2018-01-01 03:02:00 000:000:000 5.5
[9] row(s) selected.

Mach> SELECT rollup('hour', 1, time) as mtime, avg(value) FROM TAG WHERE name = 'TAG_0001' group by mtime order by mtime;
mtime                           avg(value)
---------------------------------------------------------------
2018-01-01 01:00:00 000:000:000 3.5
2018-01-01 02:00:00 000:000:000 3.5
2018-01-01 03:00:00 000:000:000 3.5
[3] row(s) selected.
Get ROLLUP MIN/MAX Value
The following example gets the minimum and maximum values for each time range of the tag. Unlike the previous example, a single query returns both the minimum and the maximum.
Mach> SELECT rollup('hour', 1, time) as mtime, min(value), max(value) FROM TAG WHERE name = 'TAG_0001' group by mtime order by mtime;
mtime                           min(value)                  max(value)
--------------------------------------------------------------------------------------------
2018-01-01 01:00:00 000:000:000 1                           6
2018-01-01 02:00:00 000:000:000 1                           6
2018-01-01 03:00:00 000:000:000 1                           6
[3] row(s) selected.

Mach> SELECT rollup('min', 1, time) as mtime, min(value), max(value) FROM TAG WHERE name = 'TAG_0001' group by mtime order by mtime;
mtime                           min(value)                  max(value)
--------------------------------------------------------------------------------------------
2018-01-01 01:00:00 000:000:000 1                           2
2018-01-01 01:01:00 000:000:000 3                           4
2018-01-01 01:02:00 000:000:000 5                           6
2018-01-01 02:00:00 000:000:000 1                           2
2018-01-01 02:01:00 000:000:000 3                           4
2018-01-01 02:02:00 000:000:000 5                           6
2018-01-01 03:00:00 000:000:000 1                           2
2018-01-01 03:01:00 000:000:000 3                           4
2018-01-01 03:02:00 000:000:000 5                           6
[9] row(s) selected.
Get ROLLUP SUM/COUNT
The following example gets the sum and the number of values. Again, a single query returns both.
Mach> SELECT rollup('min', 1, time) as mtime, sum(value), count(value) FROM TAG WHERE name = 'TAG_0001' group by mtime order by mtime;
mtime                           sum(value)                  count(value)
-------------------------------------------------------------------------------------
2018-01-01 01:00:00 000:000:000 3                           2
2018-01-01 01:01:00 000:000:000 7                           2
2018-01-01 01:02:00 000:000:000 11                          2
2018-01-01 02:00:00 000:000:000 3                           2
2018-01-01 02:01:00 000:000:000 7                           2
2018-01-01 02:02:00 000:000:000 11                          2
2018-01-01 03:00:00 000:000:000 3                           2
2018-01-01 03:01:00 000:000:000 7                           2
2018-01-01 03:02:00 000:000:000 11                          2
[9] row(s) selected.
Get ROLLUP Sum of Squares
The following example gets the sum of squares from the rollup.
Mach> SELECT rollup('sec', 1, time) as mtime, SUMSQ(value) FROM tag GROUP BY mtime ORDER BY mtime;
mtime                           SUMSQ(value)
---------------------------------------------------------------
2018-01-01 01:00:01 000:000:000 1
2018-01-01 01:00:02 000:000:000 4
2018-01-01 01:01:01 000:000:000 9
2018-01-01 01:01:02 000:000:000 16
2018-01-01 01:02:01 000:000:000 25
2018-01-01 01:02:02 000:000:000 36
2018-01-01 02:00:01 000:000:000 1
2018-01-01 02:00:02 000:000:000 4
2018-01-01 02:01:01 000:000:000 9
2018-01-01 02:01:02 000:000:000 16
2018-01-01 02:02:01 000:000:000 25
2018-01-01 02:02:02 000:000:000 36
2018-01-01 03:00:01 000:000:000 1
2018-01-01 03:00:02 000:000:000 4
2018-01-01 03:01:01 000:000:000 9
2018-01-01 03:01:02 000:000:000 16
2018-01-01 03:02:01 000:000:000 25
2018-01-01 03:02:02 000:000:000 36
[18] row(s) selected.

Mach> SELECT rollup('min', 1, time) as mtime, SUMSQ(value) FROM tag GROUP BY mtime ORDER BY mtime;
mtime                           SUMSQ(value)
---------------------------------------------------------------
2018-01-01 01:00:00 000:000:000 5
2018-01-01 01:01:00 000:000:000 25
2018-01-01 01:02:00 000:000:000 61
2018-01-01 02:00:00 000:000:000 5
2018-01-01 02:01:00 000:000:000 25
2018-01-01 02:02:00 000:000:000 61
2018-01-01 03:00:00 000:000:000 5
2018-01-01 03:01:00 000:000:000 25
2018-01-01 03:02:00 000:000:000 61
[9] row(s) selected.
ROLLUP for JSON SUMMARIZED
With value JSON SUMMARIZED, you can run ROLLUP aggregation on the full value document without defining separate JSON paths.
This is useful when one JSON document contains multiple numeric leaves such as metrics, coordinates, or counters. The result keeps the object shape and aggregates only numeric leaves.
Supported Scope
- DDL:
value JSON SUMMARIZED - Aggregates:
AVG(value),MIN(value),MAX(value),SUM(value),SUMSQ(value) - Counts:
COUNT(value),COUNT(*) FIRST(time, value)andLAST(time, value)are available only onEXTENSIONrollups.
Representative Examples
-- Aggregate the full JSON document with the default rollup
CREATE TAG TABLE tag_json_rollup (
    name  VARCHAR(20) PRIMARY KEY,
    time  DATETIME BASETIME,
    value JSON SUMMARIZED
) WITH ROLLUP;

INSERT INTO tag_json_rollup VALUES ('HVAC_A', '2026-04-07 12:00:00', '{"metrics":{"temp":20,"pressure":1000},"location":{"x":6},"status":"ok"}');
INSERT INTO tag_json_rollup VALUES ('HVAC_A', '2026-04-07 12:00:01', '{"metrics":{"temp":22,"pressure":1002},"location":{"x":8},"status":true}');
INSERT INTO tag_json_rollup VALUES ('HVAC_A', '2026-04-07 12:00:02', '{"metrics":{"temp":24,"pressure":1004},"location":{"x":10},"status":null}');
-- If needed, use ROLLUP_FORCE or WAKEUP to collect immediately

SELECT rollup('hour', 1, time) AS mtime,
       COUNT(value), MIN(value), MAX(value), AVG(value), SUM(value), SUMSQ(value)
  FROM tag_json_rollup
 WHERE name = 'HVAC_A'
 GROUP BY mtime
 ORDER BY mtime;
-- Aggregate only numeric leaves when strings, booleans, and nulls are mixed in
CREATE TAG TABLE tag_json_mix (
name VARCHAR(20) PRIMARY KEY,
time DATETIME BASETIME,
value JSON SUMMARIZED
) WITH ROLLUP TAG_PARTITION_COUNT=1;
INSERT INTO tag_json_mix VALUES ('HVAC_B', '2026-04-07 13:00:00', '{"metrics":{"temp":10,"pressure":100},"location":{"x":1},"mode":"AUTO","enabled":false}');
INSERT INTO tag_json_mix VALUES ('HVAC_B', '2026-04-07 13:00:01', '{"metrics":{"temp":20,"pressure":200},"location":{"x":2},"mode":"MANUAL","enabled":true}');
INSERT INTO tag_json_mix VALUES ('HVAC_B', '2026-04-07 13:00:02', '{"metrics":{"temp":30,"pressure":300},"location":{"x":3},"mode":null,"enabled":null}');
-- If needed, use ROLLUP_FORCE or WAKEUP to collect immediately
SELECT rollup('hour', 1, time) AS mtime, COUNT(value), COUNT(*), AVG(value), MIN(value), MAX(value), SUM(value)
FROM tag_json_mix
GROUP BY mtime
ORDER BY mtime;-- Arrays are not flattened, and FIRST/LAST requires an EXTENSION rollup
CREATE TAG TABLE tag_json_mix2 (
name VARCHAR(20) PRIMARY KEY,
time DATETIME BASETIME,
value JSON SUMMARIZED
) WITH ROLLUP EXTENSION TAG_PARTITION_COUNT=1;
INSERT INTO tag_json_mix2 VALUES ('HVAC_C', '2026-04-07 14:00:00', '{"metrics":{"temp":1,"pressure":10}, "location":{"x":1}, "history":[1,2,3]}');
INSERT INTO tag_json_mix2 VALUES ('HVAC_C', '2026-04-07 14:00:01', '{"metrics":{"temp":3,"pressure":30}, "location":{"x":2}, "history":[4,5]}');
INSERT INTO tag_json_mix2 VALUES ('HVAC_C', '2026-04-07 14:00:02', '{"metrics":{"temp":5,"pressure":50}, "location":{"x":3}, "history":[6]}');
-- If needed, use ROLLUP_FORCE or WAKEUP to collect immediately
SELECT rollup('hour', 1, time) AS mtime,
COUNT(value),
AVG(value),
SUM(value),
FIRST(time, value),
LAST(time, value)
FROM tag_json_mix2
GROUP BY mtime
ORDER BY mtime;-- Build a RAW -> SEC -> MIN -> HOUR chain
CREATE TAG TABLE tag_json_chain (
name VARCHAR(20) PRIMARY KEY,
time DATETIME BASETIME,
value JSON SUMMARIZED
);
CREATE ROLLUP _tag_json_chain_sec ON tag_json_chain(value) INTERVAL 1 SEC;
CREATE ROLLUP _tag_json_chain_min ON _tag_json_chain_sec INTERVAL 1 MIN;
CREATE ROLLUP _tag_json_chain_hour ON _tag_json_chain_min INTERVAL 1 HOUR;SELECT rollup('hour', 1, time) AS mtime, COUNT(value), AVG(value), SUMSQ(value)
FROM tag_json_chain
GROUP BY mtime
ORDER BY mtime;Malformed JSON is rejected at insert time, so it never participates in rollup aggregation.
-- Invalid JSON is not inserted and therefore not aggregated
CREATE TAG TABLE tag_json_bad (
    name  VARCHAR(20) PRIMARY KEY,
    time  DATETIME BASETIME,
    value JSON SUMMARIZED
) WITH ROLLUP;

INSERT INTO tag_json_bad VALUES ('HVAC_D', '2026-04-07 15:00:00', '{"metrics":{"temp":1,"pressure":2},"location":{"x":1}}');
INSERT INTO tag_json_bad VALUES ('HVAC_D', '2026-04-07 15:00:01', '{"metrics":{"temp":1,"pressure":2},"location":{"x":1}');
-- Rows rejected at insert time are excluded from aggregation

SELECT rollup('hour', 1, time) AS mtime, COUNT(value), SUMSQ(value)
  FROM tag_json_bad
 GROUP BY mtime
 ORDER BY mtime;
Behavior Rules
- Objects are merged recursively while preserving path union.
- Only numeric leaves are aggregated.
- Strings, booleans, nulls, and arrays are excluded from numeric aggregation; arrays are not flattened.
- Missing paths are not created in the output object.
- For duplicated keys on the same path, the last value after parser normalization is kept.
COUNT(value)counts non-nullvaluerows;COUNT(*)counts all rows.
What to Check
- Verify shape retention and numeric-leaf aggregation for
rollup('sec'|'min'|'hour', ...). - Check
COUNT(value)andCOUNT(*)independently. - Ensure
FIRST/LASTis used only onEXTENSIONrollups. - Because
FIRST/LASTreturns the full original JSON document, consider network and payload size.
Get ROLLUP FIRST/LAST
The following example gets the first and last values provided by an extended rollup.
Mach> SELECT rollup('min', 1, time) as mtime, FIRST(time, value), LAST(time, value) FROM tag GROUP BY mtime ORDER BY mtime;
mtime                           FIRST(time, value)          LAST(time, value)
--------------------------------------------------------------------------------------------
2018-01-01 01:00:00 000:000:000 1                           2
2018-01-01 01:01:00 000:000:000 3                           4
2018-01-01 01:02:00 000:000:000 5                           6
2018-01-01 02:00:00 000:000:000 1                           2
2018-01-01 02:01:00 000:000:000 3                           4
2018-01-01 02:02:00 000:000:000 5                           6
2018-01-01 03:00:00 000:000:000 1                           2
2018-01-01 03:01:00 000:000:000 3                           4
2018-01-01 03:02:00 000:000:000 5                           6
[9] row(s) selected.

Mach> SELECT rollup('hour', 1, time) as mtime, FIRST(time, value), LAST(time, value) FROM tag GROUP BY mtime ORDER BY mtime;
mtime                           FIRST(time, value)          LAST(time, value)
--------------------------------------------------------------------------------------------
2018-01-01 01:00:00 000:000:000 1                           6
2018-01-01 02:00:00 000:000:000 1                           6
2018-01-01 03:00:00 000:000:000 1                           6
[3] row(s) selected.
Grouping at Various Time Intervals
The advantage of the ROLLUP clause is that you do not need DATE_BIN() to change the time interval.
To get the sum and the number of values at 3-second intervals, run the following query. The sample data has values only at second 1 and second 2 of each minute, so all of them fall into the 0-second bucket. As a result, the output matches the per-minute rollup result.
Mach> SELECT rollup('sec', 3, time) as mtime, sum(value), count(value) FROM TAG WHERE name = 'TAG_0001' GROUP BY mtime ORDER BY mtime;
mtime                           sum(value)                  count(value)
-------------------------------------------------------------------------------------
2018-01-01 01:00:00 000:000:000 3                           2
2018-01-01 01:01:00 000:000:000 7                           2
2018-01-01 01:02:00 000:000:000 11                          2
2018-01-01 02:00:00 000:000:000 3                           2
2018-01-01 02:01:00 000:000:000 7                           2
2018-01-01 02:02:00 000:000:000 11                          2
2018-01-01 03:00:00 000:000:000 3                           2
2018-01-01 03:01:00 000:000:000 7                           2
2018-01-01 03:02:00 000:000:000 11                          2
Rollup of more than 1 day
The following examples are separate from the 2018 sample above. They assume one row at 00:00:00 on every day of each queried period.
Day Rollup
Mach> SELECT ROLLUP('day', 10, time, '2023-01-01') AS mtime, COUNT(value) FROM tag WHERE time BETWEEN TO_DATE('2023-05-01') AND TO_DATE('2023-05-31') GROUP BY mtime ORDER BY mtime;
mtime                           COUNT(value)
--------------------------------------------------------
2023-05-01 00:00:00 000:000:000 10
2023-05-11 00:00:00 000:000:000 10
2023-05-21 00:00:00 000:000:000 10
2023-05-31 00:00:00 000:000:000 1
[4] row(s) selected.
Week Rollup
If origin is not specified, weeks are aggregated in the range (Thursday-Wednesday). To aggregate in the range (Sunday-Saturday), set origin to a datetime that falls on a Sunday.
Mach> SELECT ROLLUP('week', 2, time, '2024-05-05') AS mtime, COUNT(value) FROM tag WHERE time BETWEEN TO_DATE('2024-05-01') AND TO_DATE('2024-05-31') GROUP BY mtime ORDER BY mtime;
mtime                           COUNT(value)
--------------------------------------------------------
2024-04-21 00:00:00 000:000:000 4
2024-05-05 00:00:00 000:000:000 14
2024-05-19 00:00:00 000:000:000 13
Month Rollup
origin must always be the first day of a month (the 1st).
Mach> SELECT ROLLUP('month', 2, time) AS mtime, COUNT(value) FROM tag WHERE time BETWEEN to_date('2024-05-01') AND to_date('2024-07-31') GROUP BY mtime ORDER BY mtime;
mtime                           COUNT(value)
--------------------------------------------------------
2024-05-01 00:00:00 000:000:000 61
2024-07-01 00:00:00 000:000:000 31
[2] row(s) selected.
Mach> SELECT ROLLUP('month', 1, time, '2024-05-05') AS mtime, COUNT(value) FROM tag WHERE time BETWEEN to_date('2024-05-01') AND to_date('2024-07-31') GROUP BY mtime ORDER BY mtime;
mtime                           COUNT(value)
--------------------------------------------------------
[ERR-02356: Origin must be the first day of the month.]
Year Rollup
Mach> SELECT ROLLUP('year', 1, time, '2022-01-01') AS mtime, COUNT(value) FROM tag WHERE time BETWEEN TO_DATE('2022-01-01') AND TO_DATE('2023-12-31') GROUP BY mtime ORDER BY mtime;
mtime                           COUNT(value)
--------------------------------------------------------
2022-01-01 00:00:00 000:000:000 365
2023-01-01 00:00:00 000:000:000 365
[2] row(s) selected.